Proof Testing: What Plant Managers Need to Know
In high-hazard industries across Australia—from onshore gas plants in the Cooper Basin to heavy mineral processing facilities in the Pilbara—functional safety systems stand between routine operations and catastrophic loss. A safety instrumented system (SIS) is engineered to transition a process to a safe state when predetermined conditions are violated. However, installing high-integrity hardware certified to AS IEC 61511 does not guarantee ongoing risk reduction. Over time, physical components degrade, mechanical linkages stick, and electronic circuits drift. Proof testing is the non-negotiable operational discipline that uncovers dangerous, dormant failures before an actual demand exposes them.
The Core Mandate: Exposing Dangerous Undetected Failures
Modern functional safety design assumes that a specific Safety Integrity Level (SIL) is maintained throughout an asset’s operating life. Reliability models base this integrity on the Probability of Failure on Demand (PFDavg), a metric directly tied to the proof test interval and the thoroughness of the test itself.
Instruments fail in two distinct modes: detected and undetected. Diagnostic diagnostics automatically catch dangerous detected failures, triggering an alarm or forcing a fail-safe condition. In contrast, dangerous undetected (DU) failures remain invisible during normal operations. A process transmitter frozen at an output within its normal 4–20 mA range or an emergency shutdown valve (ESDV) seized to its seat will provide no warning until called upon to act. The fundamental objective of a proof test is to reveal these DU failures, restoring the system to an “as-new” condition or establishing a clear baseline for corrective maintenance.
Evaluating Proof Test Coverage: The Danger of Partial Testing
Plant managers must avoid assuming that any test equates to a comprehensive validation. Proof Test Coverage (PTC)—the percentage of dangerous undetected failures revealed by a specific test procedure—rarely reaches 100% in operational field conditions.
A functional safety loop comprises three primary elements: sensor, logic solver, and final element. Historically, operations teams introduce hidden risk when testing these components in isolation or substituting true operational checks with software workarounds:
- Sensors: Forcing an analogue variable or digital input in the logic solver tests code execution, but it validates nothing about the primary sensing element, process impulse lines, or terminal wiring. Testing must apply a calibrated physical stimulus directly to the sensor.
- Final Elements: Valves and actuators account for roughly 50% to 70% of all SIS failures. Partial Stroke Testing (PST) confirms actuator movement and reduces PFD, but it does not test seat leakage, full stroke timing, or tight shutoff under process pressure.
- End-to-End Validation: Whenever feasible, execution must follow an end-to-end philosophy. Tripping the initiator should execute the entire logic sequence through to the final process isolation or motive power cut.
Operational Pitfalls That Compromise Site Safety
Even well-resourced engineering teams encounter systemic failures when managing recurring proof test programs. Under operational pressure, three routine pitfalls frequently erode safety integrity:
Uncontrolled Test Deferrals: Extending a proof test interval directly increases the PFDavg, effectively downgrading the achieved SIL rating of the loop. If turnaround constraints or supply chain delays force a deferral, it must be governed by a rigorous Management of Change (MOC) process with documented risk assessments, rather than an arbitrary administrative postponement.
Inadequate Restoration Controls: Bypassing safety loops to conduct testing is one of the highest-risk phases of plant maintenance. If a bypass is left active, an override switch remains latched, or an impulse root valve is left closed, the system is rendered entirely blind. Test procedures must include independent physical verification steps and strict hand-back protocols before equipment is returned to service.
Superficial “Pass/Fail” Documentation: Recording a simple checkmark on a work order provides zero engineering value. High-performing facilities record qualitative and quantitative data: as-found status, as-left status, trip points, valve closure times, and visual signs of packing leaks or corrosion. Without this data, reliability engineers cannot validate whether actual failure rates match design assumptions.
Closing the Functional Safety Lifecycle Loop
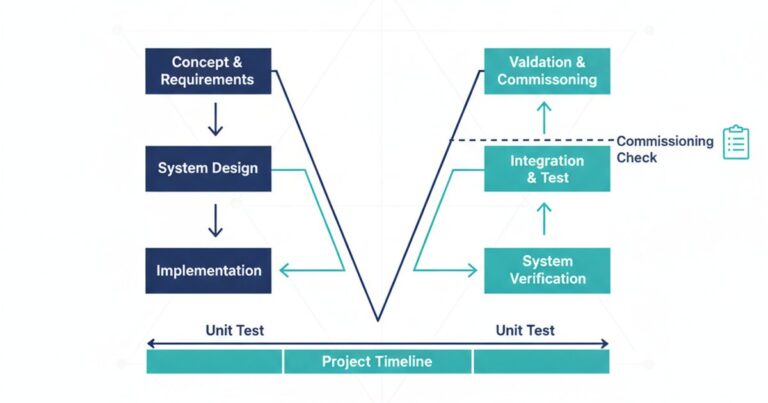
Proof testing is not an isolated maintenance obligation; it is a live validation of your Safety Requirements Specification (SRS). Under AS IEC 61511, asset owners must track operational failure data and compare it against the original reliability models. If an ESDV fails its stroke test, or an interlock drifts outside its specified tolerance twice within a year, the assumptions underpinning your safety case are invalid. You are experiencing higher failure rates than calculated, meaning your process risk is higher than accepted.
Plant leaders must establish clear workflows to capture proof test anomalies, investigate root causes, and feed operational failure rates back into functional safety assessments. This closed feedback loop protects both your personnel and your licence to operate.
Strengthening Your Proof Testing Program
Optimising proof testing intervals, establishing realistic PTC percentages, and building auditable field procedures requires deep functional safety expertise combined with hands-on operational understanding. Discover how our engineering team supports plant safety cases and life-cycle compliance across our functional safety services, or reach out directly through our contact page to review your current proof testing framework.